Azure Gateway Outage: Website Resilience Guide
A Microsoft Azure gateway incident disrupted or degraded connectivity for some customers across multiple regions for about five hours and 45 minutes between 30 September and 1 October 2026. The affected services included Azure Application Gateway and Web Application Firewall, Azure Firewall, ExpressRoute Gateway, VPN Gateway and Azure VMware Solution.
Microsoft's preliminary incident summary says a recent change to a regional gateway-management service generated higher-than-expected load while unrelated operating-system servicing progressed through multiple regions. Dependent services could not scale as expected. Microsoft paused the servicing and reverted the contributing gateway-manager change before confirming mitigation at 02:15 UTC on 1 October.
The lesson for an Australian small or medium business is not that Azure is uniquely unreliable or that every website needs an expensive active-active build. It is that cloud resilience belongs to the whole business system: ingress, identity, application, database, integrations, DNS, monitoring, people and recovery procedures. A managed service can remove operational work, but it does not define which customer journeys must survive or how quickly your organisation needs them back.
Why this Azure incident is timely
The event is useful because it affected a shared connectivity layer rather than one isolated application. A website can have healthy code and a healthy database yet still become unreachable when a gateway, firewall, private connection or control dependency is impaired.
It also crossed regional boundaries. Multi-region is often discussed as if copying an application into a second location automatically removes cloud risk. This incident is a reminder to identify whether supposedly independent regions still rely on a common management plane, gateway class, DNS path, deployment process, secret store or operations team.
Microsoft has said a fuller Post Incident Review is expected after its internal retrospective. Until then, treat the published status history as a preliminary vendor account. It supports a readiness review, not speculation about every customer's exact impact or the final root cause.
A gateway problem can surface far from the gateway
Map the customer and operational outcomes behind each network component. Technical availability is useful only when the business flow still completes.
Website access
Visitors may see timeouts, intermittent failures or pages that load while dependent APIs do not.
Forms and checkout
A page can render while submission, payment, stock, CRM or confirmation calls fail behind it.
Staff operations
Private admin, VPN, reporting or integration paths may fail even when the public site remains reachable.
Security controls
WAF and firewall dependencies affect how traffic is admitted, inspected and routed during a disruption.
Monitoring
Platform metrics may look healthy while external users in a particular geography cannot finish a task.
Recovery work
Failover can expose stale data, missing secrets, certificate gaps, DNS delays and undocumented manual steps.
Protect the customer journey, not one server
Start with recovery targets, not a cloud diagram
Before choosing zones, regions or a second provider, agree on the business outcome. Microsoft defines a recovery time objective (RTO) as the maximum acceptable downtime and a recovery point objective (RPO) as the maximum acceptable data loss measured in time.
Set these targets for individual flows rather than giving the entire website one vague label. A brochure page may tolerate several hours of disruption. A high-volume checkout, customer portal, booking service or safety-related workflow may justify much faster recovery. A contact form might degrade to a phone number or queued email, while an authenticated application may need controlled read-only access.
| Business flow | Questions to answer | Possible continuity mode |
|---|---|---|
| Public content | How long can core pages be unavailable? | Edge cache, static fallback or alternate status page |
| Lead forms | Can submissions be queued without losing consent or attribution? | Alternate form path, call-back message or read-only contact details |
| Ecommerce | What happens to carts, payments, inventory and order confirmation? | Pause checkout safely, preserve carts or switch to a tested secondary path |
| Customer portal | Which read and write actions are essential? | Read-only mode with clear freshness and support messaging |
| Integrations | Can events be replayed without duplication? | Durable queue, idempotent retry and manual reconciliation |
These targets create the budget and architecture brief. Without them, a team can spend heavily on redundancy that does not protect the important flow—or save money in the wrong place and discover the gap during an outage.
Choose the right level of redundancy
Microsoft's Well-Architected guidance distinguishes locally redundant, zonal, zone-redundant and multi-region designs. More distribution can improve resilience, but it also increases cost and operating complexity. For many production workloads, Microsoft suggests beginning with zone redundancy and asynchronous backup to another region unless stronger requirements justify more.
Single region with tested recovery
This can be reasonable for lower-criticality websites when the business accepts a longer RTO. Use infrastructure as code, restorable backups, documented DNS and certificate configuration, external monitoring and a tested rebuild process. The key is an informed acceptance of downtime—not an assumption that the platform will always recover before the business is affected.
Zone-redundant production
This is often the practical middle ground. Application capacity and supported data services span availability zones within one region. It can protect against many datacentre-level failures without the full operational burden of two live regions. Check each service's actual zone support; adding a second web instance does not make a regional database, gateway or secret dependency zone-redundant.
Multi-region active-passive
A prepared secondary region can offer faster recovery for a regional incident, but it must receive application changes, configuration, secrets and suitable data replication. Capacity, certificates, WAF rules, DNS or Front Door routing, third-party allow lists and integration callbacks must all work in the secondary path.
Multi-region active-active
This can provide very high availability and lower failover time, but the system must reconcile writes, sessions, identity, data locality and downstream integrations across regions. It is usually justified only when business impact and recovery targets outweigh the additional cost and complexity.
Find hidden shared dependencies
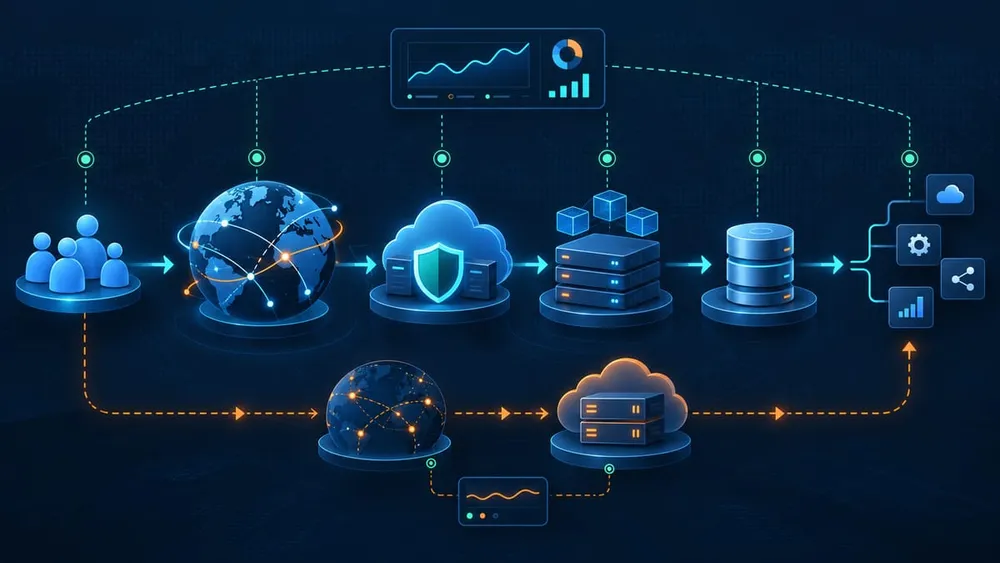
Draw the production request path from the customer's device to the final business record. Include DNS, CDN or Front Door, gateway and WAF, identity, application hosting, database, cache, storage, search, payment, CRM, email, queues, secrets, observability and deployment systems.
For every dependency, record:
- service, region, availability-zone mode and subscription or account;
- whether the dependency is data plane, control plane or both;
- what the website does when it is slow, unreachable or returns an error;
- timeout, retry, circuit-breaker and queue behaviour;
- the owner, support contact and vendor status channel;
- the secondary path and evidence that it has been tested;
- whether the failover path shares DNS, identity, gateway, secrets or deployment dependencies with production.
A second-region application that still depends on one regional database is not a complete regional failover. Two regions behind one global entry service may be appropriate, but the team should document what happens if that entry service or its configuration plane is impaired. Independence should be demonstrated through failure tests, not inferred from the architecture diagram.
Monitor from the customer's side
Microsoft recommends Azure Service Health for subscription-relevant service incidents and alerts. Configure rules for the regions and services your workload actually uses, and route them through action groups to people and incident systems that are monitored outside normal business hours. Keep the public Azure Status page as a second reference; Microsoft notes that it is designed for widespread issues and cannot know the resources in your subscriptions.
Provider alerts are only one layer. Add external synthetic checks from relevant geographies for the journeys the business depends on:
- load a representative public page and its important assets;
- resolve DNS and complete TLS from outside Azure;
- submit a safe test form and confirm the downstream record arrives;
- exercise login, search, cart or an API transaction where appropriate;
- check queue delay, integration completion and business-record creation;
- alert on latency and partial failure before the entire site is down.
Expose meaningful application health endpoints. A process that returns HTTP 200 while its database, cache, identity provider or payment dependency is unavailable is alive but not ready. Health checks should be cheap and safe, but they need enough depth to decide whether a node or region can serve production traffic.
Design a degraded mode before you need it
Resilience is not limited to moving the whole application. Sometimes the safest response is to preserve a useful subset of the service while a dependency recovers.
- Cache stable public content so service pages and critical notices remain available when the origin is impaired.
- Queue non-urgent writes where consent, ordering and replay can be preserved safely.
- Make retries bounded and idempotent so a recovery does not duplicate orders, leads, emails or payments.
- Use circuit breakers to stop repeated calls to a dependency that is persistently failing. Microsoft notes that this can prevent resource waste and support graceful degradation.
- Provide read-only modes for workflows where stale-but-labelled information is safer than a complete outage.
- Keep an alternate status and contact channel outside the affected application path.
Do not improvise these behaviours during an incident. Each fallback needs customer messaging, privacy and security review, operational ownership, reconciliation steps and a clear exit condition.
Define the failover decision
Failover is a business decision supported by technical evidence. Microsoft warns that rushed action can make an incident worse and that failover may introduce data loss, downtime, DNS delay and cost. Write the activation criteria before the outage.
| Decision input | Evidence | Owner |
|---|---|---|
| Customer impact | Failed transactions, affected regions, error rate and business volume | Incident lead with business owner |
| Provider scope | Service Health notice, tracking ID, affected services and expected updates | Cloud operations |
| Recovery target | Flow RTO, RPO and time already consumed | Business owner |
| Secondary readiness | Replication health, capacity, secrets, certificates, WAF, DNS and dependency checks | Technical recovery lead |
| Data risk | Replication lag, in-flight writes, duplicate processing and reconciliation plan | Application and data owners |
| Communication | Internal update, customer notice, support script and status page | Communications owner |
Also define failback. Moving home can be as risky as moving away: data written in the secondary location must be reconciled, traffic needs a controlled transition and the recovered primary must be verified before it receives customers again.
Turn the incident into evidence of readiness
Use a short, owned sequence that improves visibility first, then architecture and recovery.
Week 1: map
List critical journeys, Azure services, regions, shared dependencies, owners and current customer impact signals.
Week 1: alert
Configure Service Health and external synthetic alerts with tested after-hours delivery and escalation.
Week 2: set targets
Agree flow-level RTO, RPO, degraded modes and the business threshold for failover.
Week 2: close gaps
Fix missing health endpoints, unsafe retries, single-instance services, stale backups and undocumented secrets.
Week 3: rehearse
Run a controlled dependency failure and recovery drill, including people, communications and reconciliation.
Week 4: decide
Record whether single-region, zone-redundant or multi-region architecture fits the business impact and budget.
Test recovery as an end-to-end business exercise
Microsoft's continuity guidance says recovery testing should include the human process, not only infrastructure. Use a production-safe drill or an isolated environment to simulate the failure of an origin, gateway path, region or critical dependency.
A useful drill should prove:
- alerts reach the on-call owner and open an incident record;
- the team can identify the affected customer journeys and vendor scope;
- the recovery lead can activate the intended fallback without searching for credentials or instructions;
- the secondary environment has capacity, current code, valid certificates, secrets and security rules;
- database and message replication satisfy the agreed RPO;
- DNS or traffic routing changes complete within the measured RTO;
- forms, login, payments, integrations and scheduled work complete in the recovered state;
- customer and staff communications are timely and accurate;
- failback and reconciliation restore the normal environment without losing or duplicating work.
Record actual timings and evidence. If the drill takes three hours, a one-hour RTO is an aspiration, not a demonstrated capability. Fix the slowest dependencies, rehearse again and update the plan whenever the architecture or team changes.
Questions to ask your cloud or support partner
- Which customer journeys depend on Application Gateway, WAF, Firewall, VPN or ExpressRoute?
- Which resources are zonal, zone-redundant, regional or multi-region in the deployed configuration?
- What shared control-plane, DNS, identity, secret, gateway and deployment dependencies remain?
- What are the agreed RTO and RPO for checkout, forms, portal access and integrations?
- Which Service Health and external journey alerts are configured, and who receives them after hours?
- What degraded modes work without the affected dependency?
- Who can authorise failover, and what evidence must they review?
- When was failover and failback last tested end to end?
- How are data replication lag, queued events and duplicate writes reconciled?
- What is the estimated monthly cost and operational effort of the proposed resilience level?
A strong provider should answer with deployed configuration, monitoring evidence, recovery records and test results—not only a generic statement that Azure is highly available.
Sources checked
- Microsoft Azure status history: 30 September 2026 gateway incident
- Microsoft Learn: What to do during an Azure service disruption
- Microsoft Azure Well-Architected Framework: Using availability zones and regions
- Microsoft Learn: Business continuity, high availability and disaster recovery
- Microsoft Learn: Service Health alerts
- Microsoft Azure Architecture Center: Health Endpoint Monitoring pattern
- Microsoft Azure Architecture Center: Circuit Breaker pattern
- Microsoft Learn: Azure Front Door best practices
- Australian Government business.gov.au: Develop an emergency management plan
Sources were accessed on 8 October 2026. Microsoft's status entry is a preliminary incident summary; review the final Post Incident Review when it becomes available and update workload decisions if the evidence changes.