Bing AI Grounding Controls: Website Migration Guide
Prepare for Bing's new AI training and grounding controls with a practical website audit, CMS implementation, testing and migration plan.
Microsoft announced new Bing controls on 30 October 2026 that separate AI training from AI grounding. A website can allow its public content to inform generated answers while expressing a different preference about using that content to train future models. That distinction matters because Microsoft says restricting grounding will significantly reduce visibility in AI-generated experiences, even though ordinary Bing search eligibility is unchanged.
The change is especially important for sites using NoArchive or NoCache. Temporary grounding transition settings open in Bing Webmaster Tools on 15 December 2026, the new preferences begin taking effect from 1 February 2027, and qualifying sites that want to preserve grounding restrictions need page-level settings plus the temporary Webmaster Tools preference by 1 March 2027.
This is not a reason to add another directive everywhere. It is a governance decision. Business owners, marketing teams, publishers and developers should decide which public content may support AI answers, which content may be used for training, and where contractual, privacy or commercial requirements call for a different treatment.
VaniTech supports SEO and AI search visibility, CMS implementation, cloud and edge configuration and ongoing website support.
A New AI Visibility Decision Has a Real Deadline
The announcement turns a broad content-policy debate into a website configuration and CMS rollout that teams can plan now.
30 October 2026
Microsoft announced independent AI Training and AI Grounding preferences.
1 February 2027
Bing begins honouring the new preferences as pages are crawled.
1 March 2027
Legacy NoArchive and NoCache sites face the transition deadline if they want to maintain grounding restrictions.
What Bing is changing
The new model separates three questions that are often mixed together:
- Can Bingbot crawl the page? Traditional robots.txt access rules still answer this.
- Can the content be used to train generative models? The new AI Training preference answers this.
- Can the content inform a generated answer when a user asks a question? The new AI Grounding preference answers this.
Microsoft says both usage preferences default to Allow when no applicable setting is published. Training and grounding are independent, so a business can disallow training while continuing to allow grounding. That can preserve eligibility for citations and links in AI-generated experiences without expressing permission for model training.
The controls are preferences about content use, not security controls or commercial licences. Microsoft states that they do not establish licensing or payment arrangements. They also do not grant access to protected material. Authentication, authorisation and normal application security still decide who can reach private content.
Training, grounding and crawl access are different controls
| Control | Purpose | Where it is set | Business effect |
|---|---|---|---|
| Crawl access | Controls whether a crawler may retrieve a path | robots.txt for the crawler product token | Blocking can prevent indexing and discovery |
| AI Training | Expresses whether content may modify a generative model | robots.txt by site or path, or page-level meta/header | Can be restricted independently of grounding |
| AI Grounding | Expresses whether content may inform generated responses | Page-level meta tag or HTTP response header only | Restriction significantly reduces AI-result visibility |
| Traditional search indexing | Controls whether a page can appear in ordinary search results | Indexing directives such as noindex | Separate from the new usage preferences |
An Allow usage preference cannot reopen a page Bingbot cannot crawl. Conversely, blocking AI training through the purpose-specific preference does not require blocking the crawler from public pages.
The cross-vendor __usage_ai-training policy-token design is documented in an active Internet-Draft dated 30 October 2026. Treat it as work in progress rather than a completed RFC. The underlying Robots Exclusion Protocol is standardised in RFC 9309, which also warns that robots.txt is not an access-control mechanism.
Start with a directive inventory
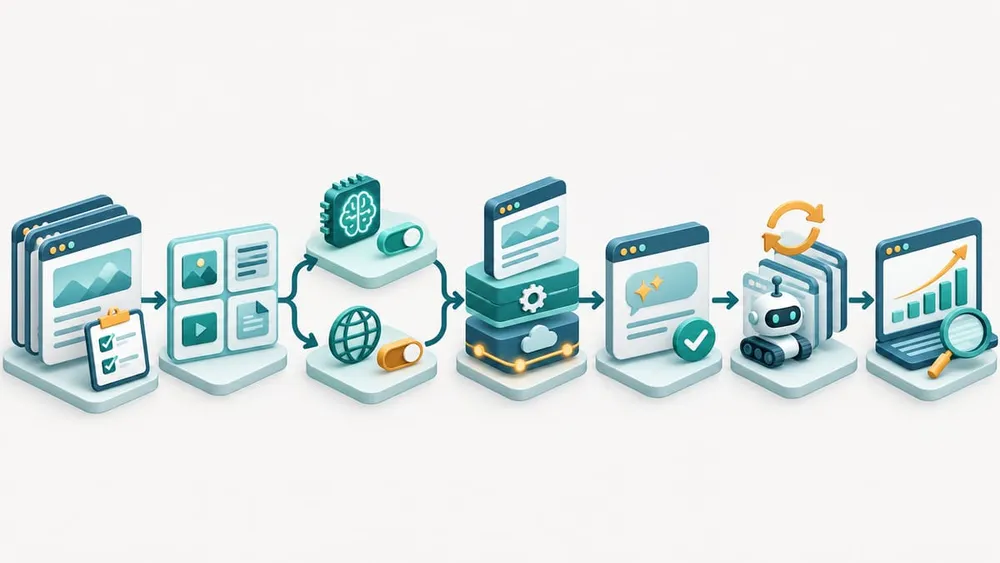
Do not begin by editing a global robots.txt file. First identify where the current behaviour comes from. A site may set directives in several layers:
- CMS page settings, templates or SEO plugins;
- server-side application middleware;
- CDN or reverse-proxy response-header rules;
- static files committed with the website;
- security tooling that changes bot behaviour;
- third-party platforms for shops, portals, help centres or campaign pages.
Crawl representative URLs and capture the final HTML, HTTP response headers and effective robots.txt file. Search for NoArchive, NoCache, NoIndex, Bingbot-specific rules and broad bot blocks. Record the source system and owner for each directive. A CMS screen is not proof if an edge rule overwrites the response after rendering.
Build the inventory by content class, not only by URL. Useful classes include service pages, product pages, articles, public documentation, gated resources, account areas, legal pages, user-generated content and paid publisher content.
Choose preferences by business purpose
The right setting depends on what the content is for. The table below is a decision aid, not legal advice or a universal policy.
| Content class | Likely visibility goal | Questions before deciding |
|---|---|---|
| Public services and product information | Usually keep grounding eligible | Is the information accurate, current and useful when quoted outside its page? |
| Public guides and support articles | Often valuable for grounding and citations | Does the page identify the business, date, author and next step clearly? |
| Subscriber or ad-funded publishing | May need a selective policy | Does AI use support discovery or weaken the commercial model? |
| Licensed or partner-supplied material | Follow the actual rights and contract | Does the organisation have authority to express a usage preference? |
| Account, staff or customer data | Protect with authentication, not robots directives | Why is the page publicly reachable at all? |
| Outdated, duplicated or low-quality pages | Fix, consolidate or retire them | Would grounding amplify information the business no longer endorses? |
For many SMEs, a practical starting point is to keep authoritative public service, product and support content eligible for grounding, decide training separately, and remove accidental legacy restrictions. Where the business wants to withhold grounding, document the reason and expected visibility trade-off.
Implement the AI Training preference
Microsoft documents two implementation paths. For a site-wide or path-level preference, use the purpose-specific group in robots.txt:
# Disallow AI training for the whole site
User-Agent: __usage_ai-training
Disallow: /

# Or disallow one path while allowing another
User-Agent: __usage_ai-training
Disallow: /resources/licensed/
Allow: /resources/public/
At page level, Microsoft documents a Bingbot meta directive or equivalent response header:
<meta name="Bingbot" content="ai-training:disallow">

X-Robots-Tag: Bingbot: ai-training:disallow
Use one governed source of truth where possible. If a CMS field writes a meta tag and the CDN also writes a header, define which layer wins and test conflicts. Keep ordinary Bingbot crawl rules separate. The policy token expresses a usage preference; it is not the bot identity that arrives in a request.
Implement the AI Grounding preference
Grounding is page-level only. Microsoft documents three outcomes:
- Allow: the default when no preference is published; content may inform generated responses.
- DisallowExtended: permit grounding in Microsoft-operated experiences but not grounding services Microsoft provides to third parties.
- Disallow: do not use the page to inform generated responses.
A page-level disallow can be published as:
<meta name="Bingbot" content="ai-grounding:disallow">

X-Robots-Tag: Bingbot: ai-grounding:disallow
Use ai-grounding:disallowextended for the middle option. Do not invent a site-wide robots.txt grounding group: Microsoft explicitly says grounding is page-level. If the policy applies to a content type, the CMS should generate the page directive consistently while still allowing an authorised exception for an individual entry.
Microsoft cautions that either restrictive grounding value significantly reduces visibility in AI-generated experiences. That may be intentional, but it should be an informed decision made by the content owner, marketing lead and technology owner together.
Plan the NoArchive and NoCache transition
The transition matters only to sites relying on the legacy directives, but those sites should not wait until March to discover where the values are generated.
- Before 15 December 2026: inventory affected pages, classify intended training and grounding outcomes, identify owners and prepare changes.
- From 15 December 2026: if the site qualifies because it uses
NoArchiveorNoCache, record the temporary grounding preference in Bing Webmaster Tools. - Before 1 February 2027: deploy the new page-level preferences and training settings, verify final responses and prepare changed-URL submissions.
- By 1 March 2027: qualifying sites that want grounding restrictions must have both the page-level AI Grounding preference and the temporary Webmaster Tools preference.
- After deployment: monitor recrawling. The temporary setting ends when Microsoft discovers the page preference, or on 30 September 2027 at the latest.
Microsoft says that after 1 March 2027, NoArchive and NoCache will no longer be read as training or grounding preferences. Do not simply remove them everywhere: they may still have another intended search presentation effect. Review the current documentation and business purpose first.
Test the rendered website, not the configuration screen
A safe rollout needs a small matrix covering representative content, conflicting layers and failure cases.
| Test | Expected evidence |
|---|---|
| Public page with default Allow | No unintended restrictive preference in HTML or headers; Bingbot is crawlable |
| Training-disallowed content type | Correct purpose-specific robots rule or page directive; ordinary crawl rules unchanged |
| Grounding-disallowed page | Exact page-level meta or X-Robots-Tag value in the final response |
| DisallowExtended exception | Middle option rendered only on authorised pages |
| CMS preview versus published page | Preference appears in production only when approved and published |
| CDN and application conflict | One documented effective value, with no duplicate or contradictory headers |
| Redirect and canonical URL | The preference is present on the final indexable page |
| Rollback | Previous configuration can be restored without changing unrelated rules |
Test production-like delivery because CDNs, caching, rendering modes and plugins can differ between local, staging and live sites. Keep response captures with the change record, and retest after CMS, SEO-plugin, hosting or CDN upgrades.
Signal changes and measure the outcome
Publishing a directive does not mean Microsoft has seen it. The preference takes effect when the page is crawled. Microsoft says IndexNow can signal that a URL changed and increase the chance of recrawling, but it does not guarantee a date. Submit changed URLs, keep them internally linked and confirm robots rules still permit retrieval.
Use Bing Webmaster Tools AI Performance as a directional monitoring layer. Microsoft documents total citations, average cited pages, sampled grounding queries, page-level citation activity and visibility trends. Topics Portfolio can add topic clusters and opportunity queries when the site has sufficient data. Microsoft labels it beta and says classification and ecosystem measures can be approximate.
Pair platform data with website analytics and business outcomes. Track visits from AI surfaces where identifiable, assisted conversions, form or checkout completion, branded demand and support deflection. A policy is successful when it matches the organisation's intended use and supports measurable business goals—not merely when a tag is present.
Move From Policy Decision to Verified Rollout
A short staged plan gives marketing, content and technical owners time to make the decision explicit and test the delivery path.
Week 1: Inventory
Find current directives, affected platforms, content classes and accountable owners.
Week 2: Decide
Choose training and grounding outcomes separately and document exceptions.
Week 3: Implement
Add governed CMS or edge controls and test final HTML, headers and robots rules.
Week 4: Verify
Deploy, submit changed URLs, record evidence and establish visibility monitoring.
Bing AI Training and Grounding FAQs
Answers for website owners planning the new controls and the legacy-directive transition.
Sources checked
- Microsoft Bing: clearer preferences for training and grounding — announcement, syntax, visibility effects and transition dates.
- Bing Webmaster Tools: New AI Preferences — control locations, options and transition summary.
- Bing Webmaster Guidelines — crawl, indexing and legacy directive context.
- Bing Webmaster Blog: AI Performance public preview — citation, page, query and trend metrics.
- Bing Webmaster Blog: Topics Portfolio beta — topic and opportunity reporting with stated limitations.
- Bing Webmaster Tools: IndexNow — changed-URL signalling context.
- IETF Datatracker: Machine-Readable Training Preference Signal — work-in-progress policy-token design.
- RFC 9309: Robots Exclusion Protocol — robots.txt semantics and security limits.
Sources were accessed on 5 November 2026. Product controls and transition guidance can change; confirm the current Bing documentation and Webmaster Tools interface before deployment.
Need Help Auditing AI Search Controls?
VaniTech can review crawler and usage directives, implement governed CMS controls and verify that public content is visible exactly where your business intends.