Cloudflare AI Search: Practical Guide for SMEs
Cloudflare made AI Search generally available on 1 October 2026, with usage-based billing starting on 1 November. That creates a practical decision point for businesses considering natural-language search on a website, a customer knowledge base or an internal assistant.
The attraction is straightforward. Instead of assembling separate crawling, parsing, storage, vector indexing, keyword search, reranking and model services, a team can connect content and expose search, chat, Model Context Protocol (MCP) or embeddable website interfaces from one managed service. New instances use hybrid retrieval by default, combining semantic matching with exact-term search.
But a managed retrieval layer does not fix unclear content, weak permissions, stale product information or an undefined customer problem. The useful question is not “Can we add AI search?” It is “Can we create a search experience that is accurate, current, appropriately secured and worth its operating cost?”
Why Cloudflare AI Search is trending now
The October general-availability release moves AI Search from an emerging capability into a service that businesses can assess for production use. Cloudflare added multimodal image retrieval, optical character recognition for scanned PDFs, larger limits for some document types and clearer pricing. It also confirmed that billing begins on 1 November 2026.
The timing reflects a broader business need. Traditional website search is good at exact product names, part numbers and error codes, but it often fails when a customer describes an intent in different words. Pure semantic search can understand intent but miss an exact identifier. Hybrid search runs keyword and vector retrieval together, then combines the ranked results.
For an SME, that can make existing content more useful without immediately commissioning a large custom retrieval platform. The strongest cases are bounded: a support centre, technical documentation, a product catalogue, policies, service information or an internal knowledge collection with clear owners.
Where managed AI search can create value
Start with a defined information problem and a content set you can own, measure and improve.
Website discovery
Help visitors find services, products, policies or technical answers when they do not know the exact terminology used on the site.
Support knowledge
Retrieve troubleshooting steps, product documentation and current procedures before generating or displaying an answer.
Internal operations
Search approved manuals, process documents and reference material behind authenticated access for staff or business agents.
Visual and document search
Use OCR and multimodal retrieval where useful information lives in scanned PDFs, diagrams, screenshots or product imagery.
What Cloudflare AI Search actually provides
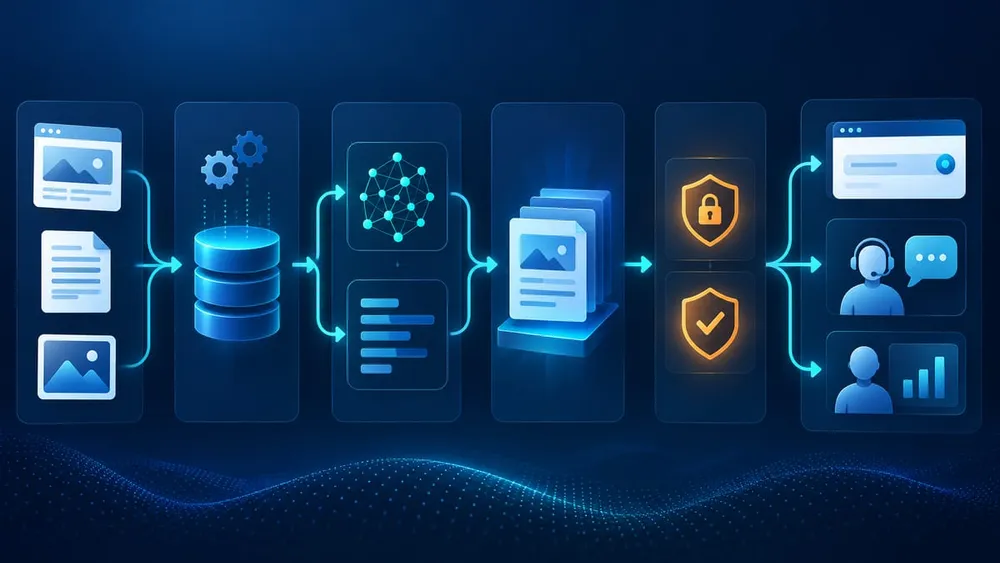
AI Search can index a website, an R2 bucket or files uploaded to built-in storage. For a website source, Cloudflare fetches pages, converts them to Markdown, splits them into chunks and builds the search indexes. External sources sync automatically every six hours by default, and the interval can be configured from 15 minutes to 24 hours.
The retrieval layer supports vector, full-text and hybrid modes. Vector search is useful when two phrases express the same intent. Full-text search is useful when exact words matter. Hybrid search runs both and fuses their ranked results, which is why it is now the default for new instances.
Teams can return source chunks through search, generate a response through chat, connect an agent through the built-in MCP endpoint or add pre-built search and chat components to a website. Generation is optional. A business can use retrieval results in an existing application and keep control over how answers are composed and presented.
Cloudflare also exposes metadata filters, relevance boosting, reranking, query rewriting, similarity caching and result thresholds. These are useful controls, but they require testing against real customer questions rather than tuning by intuition.
Good AI search starts before the query
Prepare the content before you tune the AI
Retrieval quality cannot exceed the quality of the source material. Before building an index, identify the authoritative source for each answer and remove content that is duplicated, obsolete, contradictory, legally restricted or written only for internal context.
For website sources, Cloudflare supports two crawl approaches. The default sitemap mode reads the sitemaps declared in robots.txt or configured for the instance. It can use a page's last-modified value to pick up updates. Discovery mode follows links as well as sitemaps and uses a cache-age setting, but it can stop at configured depth or page limits.
A practical content-readiness review should cover:
- a complete and current XML sitemap;
- accurate
lastmodvalues when sitemap mode is used; - path filters that exclude account, search-result, campaign-preview and low-value pages;
- content selectors that remove navigation, footers, repeated banners and unrelated interface text;
- clear headings, descriptive page titles and meaningful link text;
- metadata for content type, audience, product, region, language, version and status;
- an owner and review date for every high-value information set.
If a team cannot say which page is authoritative, an AI search system may retrieve both versions confidently. Content governance is therefore part of the search architecture, not a separate editorial clean-up.
Set privacy and access boundaries before indexing
Public website content, customer-only documentation and internal business records should not automatically share one access model. Cloudflare supports public endpoints, custom domains and Cloudflare Access, so the design can require authentication before a user or agent searches protected material.
For Australian organisations covered by the Privacy Act, OAIC guidance is a useful baseline. APP 3 requires organisations to limit personal-information collection to what is reasonably necessary and adopt a data-minimisation approach. Publicly available information is not exempt from those responsibilities. APP 11 requires reasonable technical and organisational security measures and active decisions about destroying or de-identifying information that is no longer needed.
Apply those principles to the index:
- do not ingest customer records, form submissions or support transcripts merely because they are technically accessible;
- separate public, customer and staff content into appropriate instances or permission boundaries;
- protect non-public endpoints with identity controls and least-privilege service credentials;
- exclude secrets, draft commercial material and personal data from crawls and uploads;
- document retention, deletion and re-indexing behaviour when source records change;
- log administrative changes and regularly review who can alter the source, index and endpoint.
Read VaniTech's website data guide for a broader review of forms, analytics, connected systems and retention.
Test retrieval quality, not just the demo
A polished answer to three hand-picked prompts is not an acceptance test. Build a question set from real site-search terms, support tickets, sales conversations and staff requests. Include exact identifiers, natural-language questions, ambiguous requests, outdated terminology, misspellings, unsupported topics and questions the system should refuse.
Score each result on five dimensions:
- Coverage: did the required source enter the index?
- Relevance: did the best source appear near the top?
- Grounding: does any generated answer stay within the retrieved evidence?
- Freshness: does the result reflect the current approved version?
- Safety: is restricted or irrelevant material excluded?
Cloudflare lets teams change match thresholds and the maximum number of retrieved chunks. If no result clears the configured threshold, AI Search does not generate a response. That behaviour is valuable: a deliberate “I could not find an approved answer” is often safer than a plausible answer assembled from weak evidence.
Track failed searches, zero-result questions, poor clicks, escalations and content gaps after launch. Search quality is an operating process shared by content, support, product and technology teams.
Understand the cost model before November billing
Cloudflare says every account will receive monthly included usage: 5 million ingestion tokens, 10 GB-month of storage, 1,000 semantic queries and 1,000 full-text queries. Beyond those amounts, the published rates are $0.75 per million base-ingestion tokens, an additional $0.50 per million image-processing tokens, $2.00 per GB-month of storage, $0.75 per 1,000 semantic, vector or hybrid queries, and $0.10 per 1,000 full-text queries.
Those unit rates are only the start of a forecast. Ingestion is counted after parsing and chunking, and overlapping text is counted in every chunk where it appears. A large crawl, frequent content changes, image processing and repeated re-indexing can therefore influence cost. Generation, query rewriting and external model providers may also create charges outside the core retrieval line items.
Build a forecast with at least four scenarios: pilot, normal traffic, campaign peak and misuse or bot traffic. Measure indexed tokens, storage growth, search-mode mix, generated-answer volume and cache effectiveness. Add budget alerts and a named owner before public launch.
For a small, well-bounded knowledge base, included usage may cover a meaningful pilot. For a large public site or high-volume support experience, production cost should be estimated from observed behaviour rather than a spreadsheet assumption.
When to use Cloudflare AI Search—and when not to
It is a strong candidate when
- the source content is already on Cloudflare-managed websites or R2;
- the team wants managed hybrid retrieval without operating a separate vector database and parsing pipeline;
- website, API, agent and MCP access need to share one governed index;
- content changes often enough that automated synchronisation is valuable;
- the business can test relevance and assign ongoing ownership.
Consider another approach when
- the data cannot be placed within the service's approved security or residency boundary;
- the use case requires complex record-level permissions that cannot be expressed safely in the chosen architecture;
- search depends on live transactional state rather than indexed content;
- the organisation needs specialised ranking, analytics or model control beyond the available configuration;
- the content set is so small and stable that ordinary site search or curated navigation solves the problem more simply.
A build-versus-buy decision should compare total ownership: implementation, content preparation, security review, testing, monitoring, model usage, vendor limits, support and exit options. Managed infrastructure reduces engineering work; it does not remove product ownership.
A 30-day pilot plan for an Australian SME
Week 1: Define the job
Choose one audience, one content set and one measurable problem. Record baseline search success, support effort or content-findability metrics. Nominate a product owner, content owner and technical owner.
Week 2: Prepare and secure the source
Clean duplicates and outdated pages, fix sitemap coverage, define path exclusions and content selectors, add useful metadata and confirm the privacy boundary. Separate public and restricted content before indexing.
Week 3: Build and test
Create the instance, confirm crawl and sync behaviour, then run a representative question suite. Tune hybrid retrieval, thresholds, result limits and filters. Test exact identifiers, ambiguous questions, weak evidence and prohibited content.
Week 4: Operate a limited release
Expose the experience to a small user group or a low-risk website section. Monitor search quality, latency, index freshness, access events and cost. Document rollback, incident and support procedures. Move to a broader release only when the evidence meets the agreed acceptance criteria.
Six questions to answer before production
A useful pilot ends with evidence about the business problem, not merely a working technical demonstration.
Problem
Which user task will improve, and what baseline proves that improvement is real?
Authority
Which sources are approved, current and owned when two pages disagree?
Access
What is public, customer-only or internal, and how is each boundary enforced?
Quality
What relevance, freshness, grounding and refusal scores must the pilot achieve?
Cost
Who owns ingestion, storage, query and model budgets when usage grows?
Operations
Who monitors indexing, failed searches, content gaps, access and incidents after launch?
Sources Checked
- Cloudflare: AI Search is generally available
- Cloudflare: AI Search overview
- Cloudflare: Limits and pricing
- Cloudflare: Search modes
- Cloudflare: Website data source
- Cloudflare: Website parse types
- Cloudflare: Syncing
- Cloudflare: Configuration
- Cloudflare: Result controls
- OAIC: APP 3 collection guidance
- OAIC: APP 11 security guidance