SitecoreAI Push Sources: External Search Integration Guide
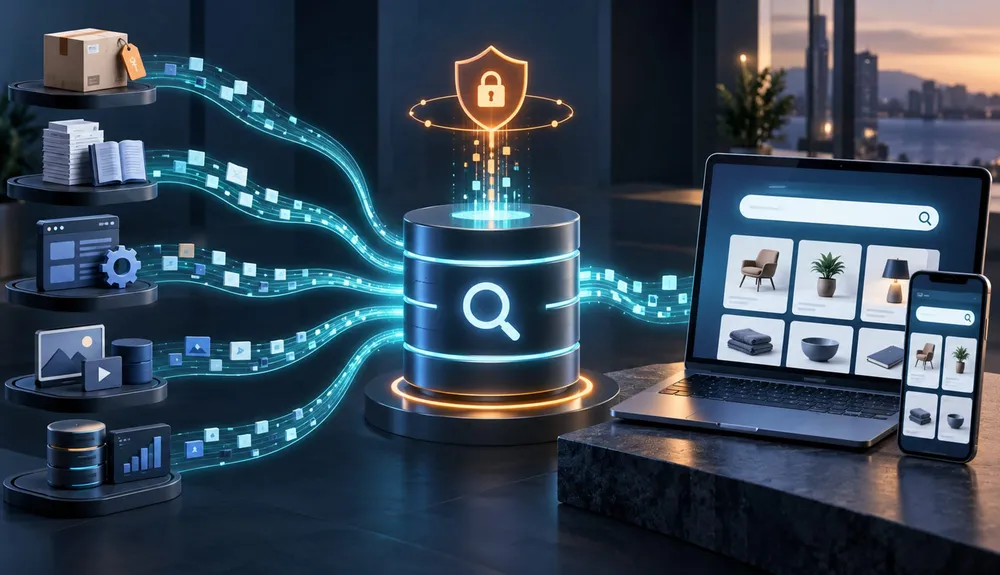
Sitecore released its Ingestion Service API on 24 September 2026 and push sources one day later. Together, they let organisations send content from external systems directly into SitecoreAI search indexes instead of depending on a website crawler or storing every searchable record in the Content editor.
That matters when useful customer information lives in a product information system, knowledge base, document platform, inventory service or custom business application. A push source can make those records available to connected search results, autocomplete and recommendation experiences while the original system remains the source of truth.
The API is not a complete integration by itself. It writes to a live index, has no dry-run or separate publish step, uses an instance-wide key and does not retain a history of submitted documents. A reliable implementation therefore needs deliberate data modelling, secure credentials, explicit deletion, repeatable full exports, reconciliation and operational ownership. This guide explains the practical decisions Australian organisations should make before switching on a production feed.
Why SitecoreAI push sources are trending now
The timing comes from two connected releases. The Ingestion Service API introduced authenticated create, update and delete operations for search indexes on 24 September. Sitecore then announced push sources on 25 September for externally maintained content, including product catalogues, knowledge bases and custom applications.
This closes a common search gap. Crawlers work well for published web pages, and content sources work when records already live in Sitecore. Neither is an ideal fit for data that changes in another platform, sits behind a login, has no crawlable page or must update independently of a website crawl. Push sources provide a dedicated API-driven path.
The feature is in a phased rollout, so availability should be confirmed in the target SitecoreAI environment. That rollout window is useful planning time: teams can identify candidate data, define a safe schema and build a replayable synchronisation process before customer-facing search depends on it.
Why this matters to business teams
Customers rarely care which platform owns a record. They expect one search box to find the right product, answer, policy, location or service. When systems are disconnected, the visible symptoms are familiar: stale prices, missing stock information, duplicated results, outdated support articles and searches that return nothing even though the business has the answer somewhere.
A well-designed push integration can reduce those gaps without forcing a costly migration of every source into the CMS. Product data can stay in the PIM or ERP. Support knowledge can stay in its approved repository. Operational records can stay in a purpose-built application. SitecoreAI receives only the fields needed for discovery and presentation.
For small and medium businesses using Sitecore or planning a broader digital platform, the commercial value is not “more API calls”. It is faster access to accurate information, fewer duplicated content processes and a clearer path for joining existing business systems to a modern website experience.
Match the index to the real system of record
The correct source type reduces duplicate ownership and makes recovery predictable.
Content source
Use when the searchable records are published structured content in Sitecore's Content editor and should follow that content lifecycle.
Site source
Use when SitecoreAI should discover public pages through crawling, sitemaps, extraction rules and URL-based identity.
Push source
Use when an external system owns the records, content cannot be crawled or updates need an API-driven synchronisation path.
Build a feed you can replay, verify and support
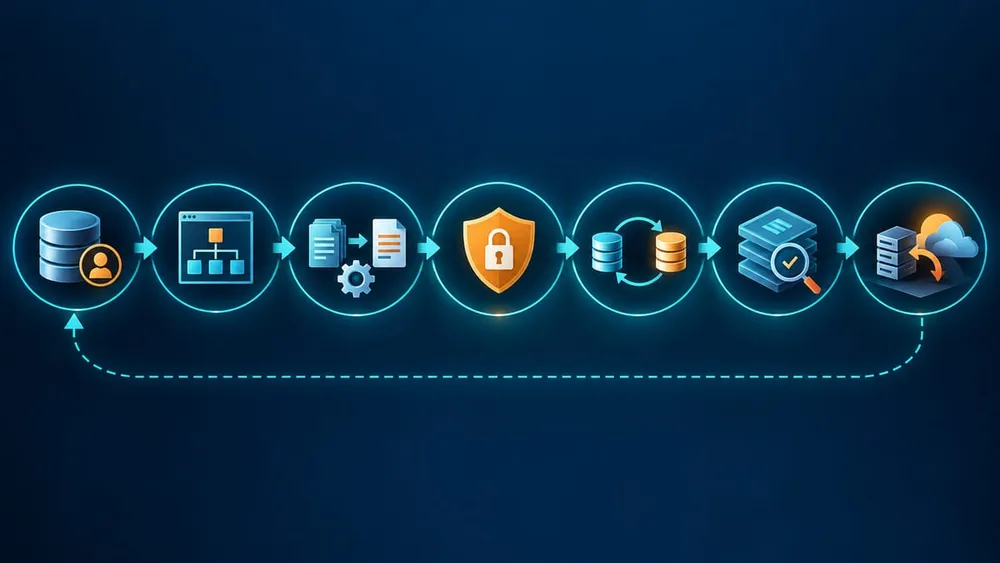
Start with ownership and a searchable data contract
Name the authoritative system before designing the API payload. If the product catalogue owns titles, availability and categories, SitecoreAI should not become a second editing surface for those values. The feed should transform approved source records into a search document and preserve an identifier that remains stable across updates.
Sitecore requires push-source fields to be defined in advance, and field names are case-sensitive. The API will not create a new field because a payload contains one. Treat the source schema as a versioned contract: document each field, source location, data type, locale, display purpose, search behaviour, privacy classification and owner.
Index the minimum useful set. A product search might need an external ID, title, summary, category, availability indicator and destination URL. It usually does not need supplier notes, cost prices, internal comments or customer details. Keeping the index narrow improves governance and reduces the impact of a mistake.
Agree how schema changes will be introduced. Adding a field may require a source configuration change, a transformation update, backfilling existing documents and search-component changes. Removing or renaming a field needs an equally deliberate migration so stale values do not remain searchable.
Respect the live-index boundary
The Ingestion Service API writes directly to the live index. Sitecore documents no dry run, preview or separate publish step for the API. That makes environment design and release controls important.
Build and validate the transformation in a non-production SitecoreAI environment first. Use representative records, unusual characters, empty optional fields, every locale and the largest expected payload. Confirm how the search component displays each field and what happens when a record is missing a URL or optional description.
For production, separate code deployment from feed activation. A practical sequence is to deploy the integration disabled, verify its configuration and secrets, submit a small allowlisted sample, review search results, then enable controlled batches. Keep a fast stop mechanism that prevents new writes without deleting the source or losing diagnostic evidence.
Do not treat a successful HTTP response as publication approval. The integration should still follow the organisation's content, product and compliance controls. Decide which source-system state makes a record eligible for search and enforce that rule before the payload reaches SitecoreAI.
Design updates and deletes as first-class events
The API supports upsert and delete. An upsert merges the fields supplied into the existing document; fields omitted from the request keep their previous values. To clear a field, Sitecore says to send an empty string. That behaviour is convenient for targeted updates, but it can also preserve stale data if a source field becomes blank and the transformer simply omits it.
Define a field-clearing policy and test it. A product discontinued by the ERP should either be deleted from the index or updated to a clearly approved state. A retired knowledge article should not remain findable because the change feed only handled creates and edits.
Use deterministic IDs from the source system and include locale where the source is configured for languages. Record the last source version or update timestamp in integration state so out-of-order messages cannot silently restore older data.
Where an event can be delivered more than once, make processing idempotent. Repeating the same source change should converge on the same indexed document rather than produce duplicates. Keep failed events in a controlled retry path and provide an operator with enough context to repair or replay them.
Batch within the API limits and handle partial outcomes
Sitecore limits a request to 1–50 operations and 512 KiB. A request exceeding either limit is rejected before indexing. Build batches by both operation count and encoded byte size; a fixed record count alone is unsafe when descriptions vary in length.
Control concurrency so a large backfill does not create an avoidable traffic spike. Apply retry delays for transient failures and cap attempts before routing a record for investigation. A permanent schema error should not be retried indefinitely.
Store a correlation ID for every batch and source record. Log the source version, action, target source, attempt number, duration and result without placing sensitive payloads or API keys in logs. Review the response at operation level so one invalid record is not mistaken for a successful batch.
Plan separate modes for ongoing changes and full synchronisation. The change feed keeps search fresh; the full export proves the integration can recover from lost state, rebuild the index or reconcile drift. Both should use the same transformation rules.
Protect an instance-wide API key
Sitecore's Push API key is instance-wide: a valid key can send documents to any source in the SitecoreAI instance. It is displayed once when created and is supplied in the Authorization header. That scope makes the key a high-value secret.
Keep it in an approved secrets-management service, inject it only into the server-side workload that performs ingestion and prevent it from reaching browser code, source control, build logs or analytics. Use separate credentials for separate environments. Restrict who can create, retrieve and rotate production secrets even when the platform's key itself is broad.
Australian secure-by-design guidance treats API keys as secrets and recommends documented ownership, protected storage, rotation and revocation processes. Give every key an owner, purpose, creation date, rotation date and emergency-revocation procedure. Test rotation before an incident forces it.
Compensate for the instance-wide scope in the integration layer. Allowlist the expected source configuration, validate the destination before every request and alert on any unexpected target. The application should fail closed rather than accept an arbitrary source identifier from an untrusted caller.
Keep personal and restricted information out of search
A search index is another place where information is stored, processed and exposed through an application. Before adding a field, ask whether it is needed for discovery or display and whether the intended search audience is authorised to see it.
OAIC APP 11 guidance says organisations holding personal information should use layered technical and organisational measures across the information lifecycle, including access security and controls for third-party providers. The safest pattern for public website search is usually not to index personal information at all.
If an authenticated search experience has a legitimate need for personal or restricted records, document the legal and business basis, minimise fields, verify access enforcement end to end and test for data leakage through suggestions, snippets, filters and logs. Do not assume that hiding a result template protects values already present in the index or API response.
Include deletion and retention in the design. Removing a record from the source system must create a reliable delete action, and the full reconciliation process must detect records that still exist in the index after they have expired upstream.
Make recovery possible without a hidden history
Sitecore documents that push sources do not retain a history of submitted documents. To rebuild an index, the integration must submit the complete document set again. This makes replayability an architectural requirement, not an optional operational improvement.
Keep the source-system query or export needed to reproduce every eligible document. Version the transformation code and record which version produced a batch. If a mapping defect is discovered, the team should be able to correct it and rebuild from authoritative data rather than depend on an opaque list of past API calls.
Be careful when using the Ingestion Service API against site or content sources. Sitecore warns that targeted additions, updates and deletions can disappear when a crawl or content re-index replaces that index. If external data must persist as the source of truth, use a push source.
Run a recovery rehearsal before launch: create a non-production source, populate it from the full export, delete or replace it, rebuild it and compare document counts and representative queries. Record the time, operator steps and business impact so recovery expectations are realistic.
Monitor search quality, not only API uptime
A healthy integration has three layers of evidence. Transport monitoring shows whether requests succeed. Data reconciliation shows whether the expected records and deletes reached the index. Search-quality monitoring shows whether customers can find useful answers.
Track batch success rate, retry volume, permanent failures, queue age and processing delay. Compare eligible source records with indexed records by count, identifier and locale. Sample changed records and verify important fields. Alert on sudden drops, unexpected growth and deletes that fail to converge.
Then watch business signals: zero-result queries, click-through from search, refinement use, product or article findability and support contacts caused by missing information. A technically successful feed can still produce poor search if titles are vague, categories are inconsistent or the ranking configuration does not match customer intent.
Assign one operational owner and a backup. Document who investigates source-data faults, transformation defects, Sitecore availability, secret rotation and search-component issues. Include the feed in normal support, release and incident processes.
Use an end-to-end test matrix
| Scenario | What to verify |
|---|---|
| Create a record | The correct ID, locale, fields and destination URL appear in search. |
| Update one field | The changed value appears and omitted fields retain their intended values. |
| Clear a field | An empty source value removes the old indexed value rather than leaving stale content. |
| Delete or retire a record | The result disappears from search, suggestions, filters and recommendations. |
| Oversized batch | The integration splits safely by operation count and byte size before calling the API. |
| Invalid schema or locale | The record is quarantined with a useful error and does not loop forever. |
| Transient outage | Retries are controlled, observable and safe from duplication. |
| Secret rotation | The new key takes effect without exposing it or causing an extended outage. |
| Full rebuild | All eligible records can be replayed and reconciled from the source of truth. |
| Access and privacy | Restricted fields never appear in public results, suggestions, logs or responses. |
Test with the real search component, not only API responses. Search rules, field mappings, filters and frontend rendering are part of the customer experience.
A practical 30-day rollout for SMEs
- Week 1 — choose the use case. Confirm feature availability, select one bounded external source and define the customer problem. Name the source-of-truth owner and production support owner.
- Week 2 — design the contract. Define deterministic IDs, locales, fields, eligibility, clearing rules, deletes, privacy classification and search-component mapping. Create non-production credentials and store them securely.
- Week 3 — build and test. Implement transformation, byte-aware batching, retries, correlation IDs, logging and a full-export mode. Run the end-to-end matrix in a non-production source.
- Week 4 — pilot and measure. Ingest a controlled production sample, verify results with business users, enable gradual synchronisation and monitor technical, reconciliation and search-quality metrics.
Keep the first use case narrow enough to recover manually if needed. A product category, one knowledge collection or a single custom application domain is better than attempting every external system at once. Reuse the proven pattern after the team can demonstrate secure operation and reliable recovery.
Who should act on this release
This topic is most relevant to Sitecore technology decision-makers, digital product owners, ecommerce teams, operations managers and integration teams whose website search depends on data outside the CMS.
It is especially worth assessing when a business maintains a product catalogue in a PIM or ERP, has a separate support knowledge base, operates a customer or partner portal, owns a searchable custom application or struggles with crawlers that cannot reach important content.
The decision is not simply whether the new API is available. It is whether the organisation can define one source of truth, expose an appropriate subset of data, secure the credential, reconcile changes and support the integration. If those responsibilities are unclear, the safest next step is a small architecture and data-governance workshop before implementation.