Machine Learning, Deep Learning and Neural Networks
Machine learning builds systems that improve a task by finding patterns in examples instead of relying only on rules written by a developer. Deep learning is a subset of machine learning that uses neural networks with multiple layers.
From examples to a model
A training dataset contains examples. Inputs are often called features; the outcome a supervised model should learn may be called a label. During training, the model adjusts internal parameters to reduce error on those examples.
Training performance is not enough. Teams normally separate data into training, validation and test sets. The test is whether the model generalises to representative examples it did not use to learn. Google’s machine-learning guidance describes overfitting as performing well on training data but poorly on new data.
What a neural network does
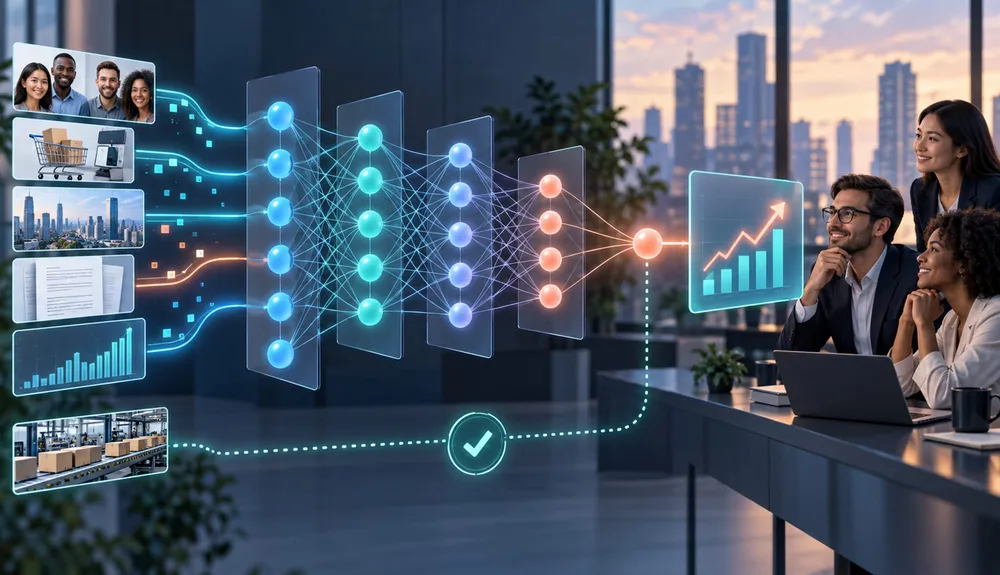
A neural network passes numerical inputs through connected layers. Each connection has a weight, and activation functions let the network represent nonlinear relationships. Training adjusts the weights so predictions produce less loss. Deep learning simply describes neural networks with enough layers and structure to learn complex representations.
The “neural” analogy is historical and loose. A production neural network is a mathematical model, not a digital brain. Its value comes from the task it can perform and the evidence that it performs reliably.
Training and inference are different
Training is the expensive learning phase. Inference is the use phase: new input goes through the trained model to produce a classification, score, recommendation or generated output. A business may use a vendor’s already-trained model and focus its own work on instructions, approved context, evaluation and integration.
Data quality shapes the outcome
Duplicate records, missing values, inconsistent labels, historical bias and data that no longer represents reality can all distort a model. More data does not automatically fix the problem. Teams need representative examples, clear definitions, controlled data pipelines and checks for changes after deployment.
A useful model must also fit the decision. Accuracy alone can hide costly false positives or false negatives. Choose measures that reflect the real workflow, then test by customer group, scenario and time period where those distinctions matter.
Machine Learning, Deep Learning and Neural Networks FAQs
Sources Checked
These primary sources were reviewed on 2026-09-17.